Faculty
Email:lichenda1996@sjtu.edu.cn
Institute:Institute of Computer Applications
MainPage:https://chenda.li/
Brief Introduction
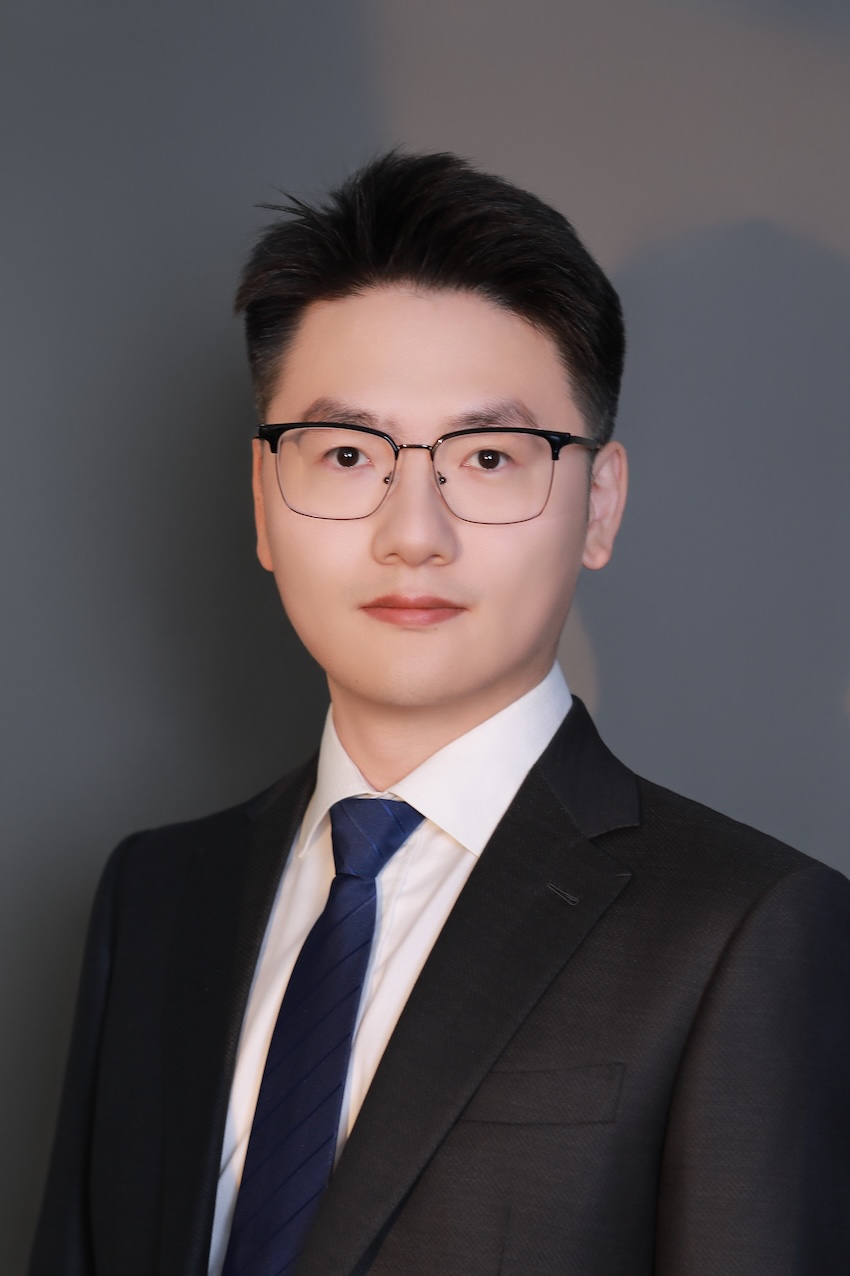
Chenda Li is an Assistant Professor and master's student supervisor in the Department of Computer Science and Engineering at Shanghai Jiao Tong University, and a member of the Auditory Cognition and Computational Acoustics Laboratory (AudioCC Lab). His research focuses on speech enhancement and separation, multimodal speech and audio processing, speech language models, and generative audio modeling. He has published more than 50 papers in international journals and conferences, including IEEE T-ASLP, ICASSP, and Interspeech. He is a core developer and maintainer of ESPnet-SE, an open-source toolkit for speech enhancement and separation, and a core organizer of the URGENT universal speech enhancement challenge series. He was selected for the Microsoft Research Asia StarTrack Program and received the Huawei Spark Award in 2025.
Personal website: https://chenda.li/; Google Scholar; GitHub.
Education
September 2020–September 2024 | Shanghai Jiao Tong University
Ph.D. in Computer Science and Technology; advisor: Prof. Yanmin Qian.
November 2023–April 2024 | Carnegie Mellon University
Visiting Scholar, WAVLab, Language Technologies Institute; host: Prof. Shinji Watanabe.
September 2018–June 2020 | Shanghai Jiao Tong University
Master's degree in Computer Science and Technology; advisor: Prof. Yanmin Qian.
September 2014–June 2018 | Huazhong University of Science and Technology
B.Eng. in Electronic Information Engineering.
Professional Experience
October 2024–present | Department of Computer Science and Engineering, Shanghai Jiao Tong University
Assistant Professor, Auditory Cognition and Computational Acoustics Laboratory (AudioCC Lab).
January 2024–present | URGENT speech enhancement challenge series
Core organizer.
June 2020–present | ESPnet-SE
Core developer and maintainer, contributing to the development and maintenance of the ESPnet speech enhancement and separation toolkit.
Teaching Assignment
Shanghai Jiao Tong University, CS1501: Programming Concepts and Methodology (C/C++)
Publications
For the latest publication list, please see Google Scholar.
1. Marvin Sach, Yihui Fu, Kohei Saijo, Wangyou Zhang, Samuele Cornell, Robin Scheibler, Chenda Li, Zhaoheng Ni, Anurag Kumar, Wei Wang, Yanmin Qian, Shinji Watanabe, and Tim Fingscheidt. “2025 Urgent Speech Enhancement Challenge Multilingual P.808 Listening Tests: Approach and Results.” ICASSP 2026, 2026, pp. 22477–22481, DOI.
2. Haiyang Sun, Chenyang Le, Wei Wang, Leying Zhang, Chuang Li, Bing Han, Chenda Li, Mengxiao Bi, and Yanmin Qian. “Beyond Sentence-Level Labels: Integrating Conversational Context and Personal Experience for Natural Emotional Expression.” Findings of the Association for Computational Linguistics: ACL 2026, 2026, pp. 18839–18854, DOI.
3. Masao Someki, Alexander Polok, Carlos Carvalho, Chyi-Jiunn Lin, Da-Hee Yang, Jiatong Shi, Jinchuan Tian, Nelson Enrique Yalta Soplin, Samuele Cornell, Siddhant Arora, Francisco Teixeira, Wei Wang, William Chen, Alberto Abad, Chenda Li, Shinji Watanabe, and Wangyou Zhang. “ESPnet3: Infrastructure for Scalable Speech and Audio Research in the Foundation Model Era.” Interspeech 2026, 2026, pp. 4767–4772, DOI.
4. Chenda Li, Wei Wang, Marvin Sach, Wangyou Zhang, Kohei Saijo, Samuele Cornell, Yihui Fu, Zhaoheng Ni, Tim Fingscheidt, Shinji Watanabe, and Yanmin Qian. “ICASSP 2026 Urgent Speech Enhancement Challenge.” ICASSP 2026, 2026, pp. 21919–21921, DOI.
5. Jiahe Wang, Hongyu Wang, Wei Wang, Lei Yang, Chenda Li, Wangyou Zhang, Lufen Tan, and Yanmin Qian. “MeanSE: Efficient Generative Speech Enhancement with Mean Flows.” ICASSP 2026, 2026, pp. 16827–16831, DOI.
6. Tianhua Li, Chenda Li, Wei Wang, Xin Zhou, Xihui Chen, Jianqing Gao, and Yanmin Qian. “SLM-SS: Speech Language Model for Generative Speech Separation.” ICASSP 2026, 2026, pp. 15432–15436, DOI.
7. Chenjun Zhao, Guangzhi Sun, Keqi Deng, Chenda Li, and Philip C. Woodland. “Str-DiffSep: Streamable Diffusion Model for Speech Separation.” ICASSP 2026, 2026, pp. 14412–14416, DOI.
8. Qinzhe Hu, Chenda Li, Wangyou Zhang, Shujie Liu, Yan Lu, and Yanmin Qian. “TF-MoE: Time-Frequency Mixture-of-Experts for Efficient Speech Separation.” Interspeech 2026, 2026, pp. 3172–3177, DOI.
9. Zhenglong Liu, Wangyou Zhang, Chenda Li, and Yanmin Qian. “Towards Array-Invariant Speech Enhancement via Geometry-Aware Dynamic Convolution.” Interspeech 2026, 2026, pp. 6974–6978, DOI.
10. Wei Wang, Wangyou Zhang, Chenda Li, Jiahe Wang, Samuele Cornell, Marvin Sach, Kohei Saijo, Yihui Fu, Zhaoheng Ni, Mengxiao Bi, Tim Fingscheidt, Shinji Watanabe, and Yanmin Qian. “URGENT-MOS: Unified Multi-Metric and Preference Learning for Robust Speech Quality Assessment.” Interspeech 2026, 2026, pp. 5689–5694, DOI.
11. Hongyu Wang, Chenda Li, Xin Zhou, Shuai Wang, and Yanmin Qian. “USE: A Unified Model for Universal Sound Separation and Extraction.” the AAAI Conference on Artificial Intelligence, 2026, pp. 33476–33484, DOI.
12. Yanmin Qian, Chenda Li, Wangyou Zhang, and Shaoxiong Lin. “Contextual Understanding with Contextual Embeddings for Multi-Talker Speech Separation and Recognition in a Cocktail Party.” npj Acoustics, 2025, pp. 3, DOI.
13. Jiahong Li, Yiwen Shao, Jianheng Zhuo, Chenda Li, Liliang Tang, Dong Yu, and Yanmin Qian. “Efficient Multilingual ASR Finetuning via LoRA Language Experts.” Interspeech 2025, 2025, pp. 1138–1142, DOI.
14. Wei Wang, Wangyou Zhang, Chenda Li, Jaitong Shi, Shinji Watanabe, and Yanmin Qian. “Improving Speech Enhancement with Multi-Metric Supervision from Learned Quality Assessment.” 2025 IEEE Automatic Speech Recognition and Understanding Workshop (ASRU), 2025, pp. 1–8, DOI.
15. Kohei Saijo, Wangyou Zhang, Samuele Cornell, Robin Scheibler, Chenda Li, Zhaoheng Ni, Anurag Kumar, Marvin Sach, Yihui Fu, Wei Wang, Tim Fingscheidt, and Shinji Watanabe. “Interspeech 2025 URGENT Speech Enhancement Challenge.” Interspeech 2025, 2025, pp. 858–862, DOI.
16. Chenda Li, Wangyou Zhang, Wei Wang, Robin Scheibler, Kohei Saijo, Samuele Cornell, Yihui Fu, Marvin Sach, Zhaoheng Ni, Anurag Kumar, Tim Fingscheidt, Shinji Watanabe, and Yanmin Qian. “Less Is More: Data Curation Matters in Scaling Speech Enhancement.” 2025 IEEE Automatic Speech Recognition and Understanding Workshop (ASRU), 2025, pp. 1–8, DOI.
17. Wangyou Zhang, Kohei Saijo, Samuele Cornell, Robin Scheibler, Chenda Li, Zhaoheng Ni, Anurag Kumar, Marvin Sach, Wei Wang, Yihui Fu, Shinji Watanabe, Tim Fingscheidt, and Yanmin Qian. “Lessons Learned from the URGENT 2024 Speech Enhancement Challenge.” Interspeech 2025, 2025, pp. 853–857, DOI.
18. Chenda Li and Yanmin Qian. “Online Generative Speech Enhancement with Diffusion Gradient Guidance.” ACTA ACUSTICA, 2025, pp. 1644–1651, DOI.
19. Jiatong Shi, Haoran Wang, William Chen, Chenda Li, Wangyou Zhang, Jinchuan Tian, and Shinji Watanabe. “PURE Codec: Progressive Unfolding of Residual Entropy for Speech Codec Learning.” 2025 IEEE Automatic Speech Recognition and Understanding Workshop (ASRU), 2025, pp. 1–8, DOI.
20. Jiahe Wang, Chenda Li, Wei Wang, Wangyou Zhang, Samuele Cornell, Marvin Sach, Robin Scheibler, Kohei Saijo, Yihui Fu, Zhaoheng Ni, Anurag Kumar, Tim Fingscheidt, Shinji Watanabe, and Yanmin Qian. “URGENT-PK: Perceptually-Aligned Ranking Model Designed for Speech Enhancement Competition.” 2025 IEEE Automatic Speech Recognition and Understanding Workshop (ASRU), 2025, pp. 1–7, DOI.
21. Wangyou Zhang, Kohei Saijo, Jee-weon Jung, Chenda Li, Shinji Watanabe, and Yanmin Qian. “Beyond Performance Plateaus: A Comprehensive Study on Scalability in Speech Enhancement.” Interspeech 2024, 2024, pp. 1740–1744, DOI.
22. Chenda Li, Samuele Cornell, Shinji Watanabe, and Yanmin Qian. “Diffusion-Based Generative Modeling With Discriminative Guidance for Streamable Speech Enhancement.” 2024 IEEE Spoken Language Technology Workshop (SLT), 2024, pp. 333–340, DOI.
23. Xin Zhou, Wangyou Zhang, Chenda Li, and Yanmin Qian. “Insights from Hyperparameter Scaling of Online Speech Separation.” ISCSLP, 2024, pp. 561–565.
24. Jiahong Li, Chenda Li, Yifei Wu, and Yanmin Qian. “Unified Cross-Modal Attention: Robust Audio-Visual Speech Recognition and Beyond.” IEEE/ACM Transactions on Audio, Speech, and Language Processing, 2024, pp. 1941–1953, DOI.
25. Wangyou Zhang, Robin Scheibler, Kohei Saijo, Samuele Cornell, Chenda Li, Zhaoheng Ni, Anurag Kumar, Jan Pirklbauer, Marvin Sach, Shinji Watanabe, Tim Fingscheidt, and Yanmin Qian. “URGENT Challenge: Universality, Robustness, and Generalizability For Speech Enhancement.” Interspeech 2024, 2024, pp. 4868–4872, DOI.
26. Chenda Li, Yao Qian, Zhuo Chen, Naoyuki Kanda, Dongmei Wang, Takuya Yoshioka, Yanmin Qian, and Michael Zeng. “Adapting Multi-Lingual ASR Models for Handling Multiple Talkers.” Interspeech 2023, 2023, pp. 1314–1318, DOI.
27. Yifei Wu, Chenda Li, and Yanmin Qian. “Light-Weight Visualvoice: Neural Network Quantization On Audio Visual Speech Separation.” ICASSP 2023, 2023, pp. 1–5, DOI.
28. Linfeng Yu, Wangyou Zhang, Chenda Li, and Yanmin Qian. “Overlap-Aware Continuous Speech Separation without Permutation Invariant Training.” Interspeech 2023, 2023, pp. 3512–3516, DOI.
29. Chenda Li, Yifei Wu, and Yanmin Qian. “Predictive Skim: Contrastive Predictive Coding for Low-Latency Online Speech Separation.” ICASSP 2023, 2023, pp. 1–5, DOI.
30. Jiahong Li, Chenda Li, Yifei Wu, and Yanmin Qian. “Robust Audio-Visual ASR with Unified Cross-Modal Attention.” ICASSP 2023, 2023, pp. 1–5, DOI.
31. Chenda Li, Yao Qian, Zhuo Chen, Dongmei Wang, Takuya Yoshioka, Shujie Liu, Yanmin Qian, and Michael Zeng. “Target Sound Extraction with Variable Cross-Modality Clues.” ICASSP 2023, 2023, pp. 1–5, DOI.
32. Chenda Li, Zhuo Chen, and Yanmin Qian. “Dual-Path Modeling With Memory Embedding Model for Continuous Speech Separation.” IEEE/ACM Transactions on Audio, Speech, and Language Processing, 2022, pp. 1508–1520, DOI.
33. Yen-Ju Lu, Xuankai Chang, Chenda Li, Wangyou Zhang, Samuele Cornell, Zhaoheng Ni, Yoshiki Masuyama, Brian Yan, Robin Scheibler, Zhong-Qiu Wang, Yu Tsao, Yanmin Qian, and Shinji Watanabe. “ESPnet-SE++: Speech Enhancement for Robust Speech Recognition, Translation, and Understanding.” Interspeech 2022, 2022, pp. 5458–5462, DOI.
34. Bowen Qu, Chenda Li, Jinfeng Bai, and Yanmin Qian. “Improving Speech Separation with Knowledge Distilled from Self-Supervised Pre-Trained Models.” ISCSLP, 2022, pp. 329–333, DOI.
35. Chenda Li, Lei Yang, Weiqin Wang, and Yanmin Qian. “Skim: Skipping Memory Lstm for Low-Latency Real-Time Continuous Speech Separation.” ICASSP 2022, 2022, pp. 681–685, DOI.
36. Wei Wang, Xun Gong, Yifei Wu, Zhikai Zhou, Chenda Li, Wangyou Zhang, Bing Han, and Yanmin Qian. “The Sjtu System For Multimodal Information Based Speech Processing Challenge 2021.” ICASSP 2022, 2022, pp. 9261–9265, DOI.
37. Yifei Wu, Chenda Li, Jinfeng Bai, Zhongqin Wu, and Yanmin Qian. “Time-Domain Audio-Visual Speech Separation on Low Quality Videos.” ICASSP 2022, 2022, pp. 256–260, DOI.
38. Yen-Ju Lu, Samuele Cornell, Xuankai Chang, Wangyou Zhang, Chenda Li, Zhaoheng Ni, Zhong-Qiu Wang, and Shinji Watanabe. “Towards Low-Distortion Multi-Channel Speech Enhancement: The ESPNET-Se Submission to the L3DAS22 Challenge.” ICASSP 2022, 2022, pp. 9201–9205, DOI.
39. Yifei Wu, Chenda Li, Song Yang, Zhongqin Wu, and Yanmin Qian. “Audio-Visual Multi-Talker Speech Recognition in a Cocktail Party.” Interspeech 2021, 2021, pp. 3021–3025, DOI.
40. Wangyou Zhang, Jing Shi, Chenda Li, Shinji Watanabe, and Yanmin Qian. “Closing the Gap Between Time-Domain Multi-Channel Speech Enhancement on Real and Simulation Conditions.” 2021 IEEE Workshop on Applications of Signal Processing to Audio and Acoustics (WASPAA), 2021, pp. 146–150, DOI.
41. Cong Han, Yi Luo, Chenda Li, Tianyan Zhou, Keisuke Kinoshita, Shinji Watanabe, Marc Delcroix, Hakan Erdogan, John R. Hershey, Nima Mesgarani, and Zhuo Chen. “Continuous Speech Separation Using Speaker Inventory for Long Recording.” Interspeech 2021, 2021, pp. 3036–3040, DOI.
42. Chenda Li, Zhuo Chen, Yi Luo, Cong Han, Tianyan Zhou, Keisuke Kinoshita, Marc Delcroix, Shinji Watanabe, and Yanmin Qian. “Dual-Path Modeling for Long Recording Speech Separation in Meetings.” ICASSP 2021, 2021, pp. 5739–5743, DOI.
43. Chenda Li, Yi Luo, Cong Han, Jinyu Li, Takuya Yoshioka, Tianyan Zhou, Marc Delcroix, Keisuke Kinoshita, Christoph Boeddeker, Yanmin Qian, Shinji Watanabe, and Zhuo Chen. “Dual-Path RNN for Long Recording Speech Separation.” 2021 IEEE Spoken Language Technology Workshop (SLT), 2021, pp. 865–872, DOI.
44. Chenda Li, Jing Shi, Wangyou Zhang, Aswin Shanmugam Subramanian, Xuankai Chang, Naoyuki Kamo, Moto Hira, Tomoki Hayashi, Christoph Boeddeker, Zhuo Chen, and Shinji Watanabe. “ESPnet-SE: End-To-End Speech Enhancement and Separation Toolkit Designed for ASR Integration.” 2021 IEEE Spoken Language Technology Workshop (SLT), 2021, pp. 785–792, DOI.
45. Pengcheng Guo, Florian Boyer, Xuankai Chang, Tomoki Hayashi, Yosuke Higuchi, Hirofumi Inaguma, Naoyuki Kamo, Chenda Li, Daniel Garcia-Romero, Jiatong Shi, Jing Shi, Shinji Watanabe, Kun Wei, Wangyou Zhang, and Yuekai Zhang. “Recent Developments on Espnet Toolkit Boosted By Conformer.” ICASSP 2021, 2021, pp. 5874–5878, DOI.
46. Yi Luo, Zhuo Chen, Cong Han, Chenda Li, Tianyan Zhou, and Nima Mesgarani. “Rethinking The Separation Layers In Speech Separation Networks.” ICASSP 2021, 2021, pp. 1–5, DOI.
47. Shinji Watanabe, Florian Boyer, Xuankai Chang, Pengcheng Guo, Tomoki Hayashi, Yosuke Higuchi, Takaaki Hori, Wen-Chin Huang, Hirofumi Inaguma, Naoyuki Kamo, Shigeki Karita, Chenda Li, Jing Shi, Aswin Shanmugam Subramanian, and Wangyou Zhang. “The 2020 ESPnet Update: New Features, Broadened Applications, Performance Improvements, and Future Plans.” 2021 IEEE Data Science and Learning Workshop (DSLW), 2021, pp. 1–6, DOI.
48. Chenda Li and Yanmin Qian. “Deep Audio-Visual Speech Separation with Attention Mechanism.” ICASSP 2020, 2020, pp. 7314–7318, DOI.
49. Chenda Li and Yanmin Qian. “Listen, Watch and Understand at the Cocktail Party: Audio-Visual-Contextual Speech Separation.” Interspeech 2020, 2020, pp. 1426–1430, DOI.
50. Chenda Li and Yanmin Qian. “Prosody Usage Optimization for Children Speech Recognition with Zero Resource Children Speech.” Interspeech 2019, 2019, pp. 3446–3450, DOI.
Project Fund
Shanghai Jiao Tong University Explore X Fund, 2025
Tencent AI Lab Rhino-Bird Focused Research Program | Selected project, 2025
Awards
2025 | Huawei Spark Award.
2025 | Selected for the Microsoft Research Asia 2025 StarTrack Program.
2025 | Outstanding Thesis Advisor, School of Computer Science, Shanghai Jiao Tong University.
2022 | First place in the 3D Speech Enhancement track of the L3DAS22 Challenge (ICASSP 2022).
2022 | Third place in the Audio-Visual Speech Recognition track of the MISP Challenge.
2021 | Best Oral Presentation, Doctoral Forum at the 16th National Conference on Man-Machine Speech Communication (NCMMSC).
Academic Service
Journal reviewing
IEEE/ACM Transactions on Audio, Speech, and Language Processing (TASLP), Speech Communication, among others.
Conference reviewing
ICASSP, Interspeech, AAAI, ACL, among others.
Address: No. 800 Dongchuan Road, Shanghai
Email: https://www.yzsfdd.com
Postal Code: 200240
Tel: +86-21-34205058 / 34204728
(Trial Version) Copyright © 2025 School of Computer Science, Shanghai Jiao Tong University. 沪交ICP备2010898
 Chinese


